Best Digital Marketing Tools in 2026: What Marketers Actually Need and What They Can Skip
Open LinkedIn for a few minutes and you will probably come across a colourful graphic…
 Harika October 6, 2026
 By Satya HemanthUpdated September 21, 202614 min read24 views
Artificial intelligence has traditionally been the outcome of human research. Engineers designed the systems, researchers planned experiments, programmers wrote the code, and teams spent months analysing failures before deciding what the next generation should improve. AI could assist with parts of that work, but the responsibility for building better AI remained overwhelmingly human.
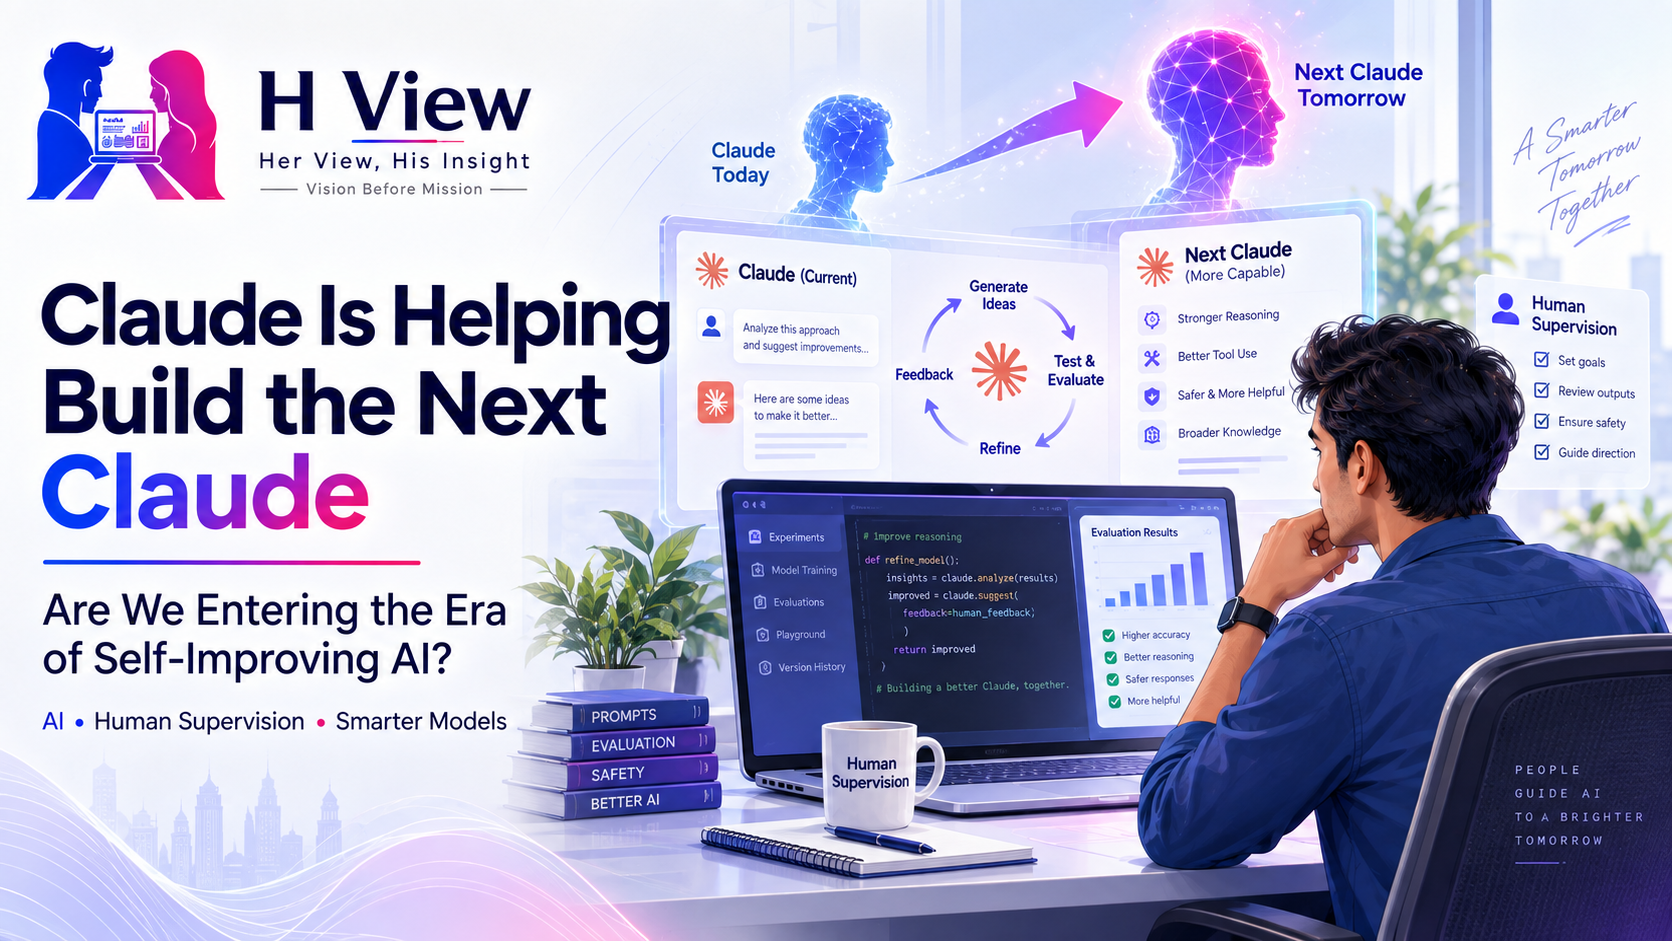
That boundary is beginning to change inside Anthropic. The company says Claude now “leads” approximately 26% of its measured AI research and development work, compared with less than 1% earlier in 2026, while more than 90% of the work measured on its internal platform involves Claude at least collaboratively. Anthropic is equally clear that Claude has not reached full autonomy in any measured category of AI R&D, so describing this as an AI independently designing and releasing its own successor would go well beyond the evidence.
Even with that qualification, something important has changed. We spent the first phase of generative AI asking how much work AI could do for programmers, researchers and employees, but we are now approaching a more unusual question: what happens when AI begins doing substantial parts of the work required to create better AI?
The phrase “Claude is building Claude” is useful for attracting attention, but it needs to be understood correctly. Anthropic still decides what models to develop, provides the computing resources, establishes the research objectives, evaluates results and controls deployment. Human researchers continue supervising Claude’s work and remain responsible for deciding whether an experiment, code change or research direction should actually influence a future model.
What has changed is the amount of work occurring between those human decisions. Anthropic describes several levels of AI involvement, ranging from no meaningful AI participation to full autonomy. At the level it calls “AI leads,” a system can receive a relatively high-level objective and complete most of the task end to end while a person supervises rather than manually performing each intermediate step. Anthropic says Claude had reached that level for about 26% of measured R&D work by August 2026.
That is very different from a researcher occasionally asking a chatbot for help. The human increasingly defines the problem, evaluates the output and makes the final judgement, while Claude performs more of the implementation, analysis and experimentation that once occupied most of the researcher’s time.
Software engineering provides one of the clearest examples because modern AI research depends heavily on code. Anthropic says Claude has become deeply involved in its internal engineering workflows, allowing researchers and developers to delegate increasingly substantial coding tasks rather than merely asking for snippets or debugging suggestions. Reuters also reported that Anthropic had about 30,000 AI agents active at a time on the internal platform covered by these measurements, with agent actions monitored for potentially dangerous behaviour.
The wider significance is that AI can potentially shorten the research cycle itself. A human researcher may still decide which hypothesis is worth testing, but Claude can help write experimental code, investigate failures, analyse results and prepare the next iteration. When those activities become faster, the same research team can explore more ideas in the same amount of time without necessarily hiring a proportionally larger workforce.
Anthropic’s recent scientific work also shows how far long-running AI tasks are progressing. In September, the company reported that Claude worked largely autonomously for 11 days to produce a computer-checked formalisation of Fermat’s Last Theorem in the Lean proof system, generating millions of lines of formal proof code and thousands of intermediate theorems. The achievement does not mean Claude discovered Fermat’s Last Theorem, which was proven by Andrew Wiles decades ago, but it demonstrates that AI systems can now remain focused on highly complex technical work for far longer than a typical chatbot interaction.
The phrase self-improving AI can mean several different things, and mixing them together creates unnecessary confusion. An AI system helping an engineer write research code is very different from an autonomous system deciding what kind of successor to build, training that successor and then allowing the new system to repeat the process without meaningful human intervention.
A simple comparison shows where the important differences lie.
| Stage | What the AI does | Current position |
|---|---|---|
| AI assistance | Helps humans with coding, research, summaries and analysis | Common today |
| AI collaboration | Completes substantial portions of a task under close direction | Already widespread |
| AI-led R&D | Completes most of a defined task from a high-level instruction while humans supervise | Anthropic says Claude leads about 26% of measured R&D |
| Autonomous AI research | Runs complete research projects with minimal human involvement | Emerging in limited experiments |
| Recursive self-improvement | Designs and develops a more capable successor that can repeat the process | Not achieved |
Anthropic itself defines recursive self-improvement much more strongly than ordinary AI-assisted development. Its research discusses a future in which AI could eventually contribute so much to developing better AI that each generation improves the process used to create the next one. The company does not claim that Claude has reached that stage today, and it explicitly notes that such an outcome is not inevitable.
The reason the current development still matters is that the earlier stages could create the pathway toward the later ones. If AI systems become increasingly capable of conducting research, writing infrastructure, evaluating experiments and solving technical problems, the amount of human effort required to produce the next model could gradually decline.
The biggest advantage of AI-assisted research is not simply that individual tasks become faster. The more consequential effect comes from increasing the number of experiments a research team can attempt and shortening the distance between an idea and a tested result.
Imagine a research group that previously needed several days to implement an experiment, debug the system, gather the results and prepare another version. If Claude can perform much of that intermediate work under supervision, researchers can spend more of their time deciding what questions are worth asking and interpreting what the results actually mean. Over an entire development cycle, even modest improvements in each step can compound into a much faster pace of progress.
Anthropic’s own recent research illustrates how broadly this approach may spread. Beyond model development, Claude has been used to optimise more than 30 open-source biomolecular modelling systems in less than four weeks, with Anthropic reporting roughly fourfold average speed improvements. That work suggests AI-assisted technical research is already expanding beyond software engineering into mathematics, biology and other scientific fields.
This is why the idea attracts so much excitement. A small group of highly skilled researchers supported by capable AI agents may eventually accomplish work that once required a much larger organisation, potentially accelerating discoveries in software, mathematics, chemistry, medicine and engineering.
The difficulty is that faster research does not automatically give humans more time to understand what is being created. If model capabilities improve faster because AI helps build each new generation, safety evaluation, regulation and internal oversight need to accelerate at roughly the same pace.
Anthropic’s own measurement work acknowledges this concern. The company proposes tracking how much AI R&D is performed by AI, how well AI agents are monitored and how computing resources are divided between capability development and safety. It also acknowledges limitations in using its own models to evaluate some of these measurements and suggests independent or cross-lab verification could eventually strengthen confidence in the results.
The underlying concern is practical rather than science-fictional. If thousands of AI agents are simultaneously writing code, running experiments and analysing results, an organisation needs monitoring systems capable of following that activity without creating the illusion of supervision while important mistakes pass unnoticed.
There is a temptation to assume that better AI reduces the need for human experts. Inside frontier AI development, the opposite may be true for the people who remain responsible for decisions because the consequences of approving flawed work become more significant as automation expands.
An AI-generated experiment can look technically convincing while testing the wrong assumption. Code may pass the obvious checks while introducing subtle vulnerabilities, and an apparently successful research result may depend on a measurement error that the system itself fails to recognise. A capable human researcher therefore needs enough understanding of the underlying work to challenge Claude rather than functioning only as an approval layer.
This creates a difficult long-term question about skill retention. If AI performs most of the implementation work for years, researchers may become more productive while gradually gaining less firsthand experience with the underlying processes. Organisations will need to think carefully about how they preserve human expertise so that supervision remains meaningful rather than ceremonial.
The next major threshold may not be whether AI can write more code. It may be whether an AI system can decide which problems deserve attention without waiting for a human researcher to define the objective first.
There is an important difference between asking Claude to fix a known problem and asking it to inspect a system, identify the most consequential weakness and design an improvement. An even more advanced stage would involve Claude deciding which research direction should be prioritised across an entire programme, allocating resources and evaluating competing strategies with only high-level human guidance.
Anthropic’s recursive self-improvement research discusses this progression because strategic research judgement is much closer to genuine scientific autonomy than ordinary task completion. We have not reached a stage where frontier models independently control entire AI-development programmes, but the movement from assistance toward increasingly broad delegation makes the question less theoretical than it once appeared.
The evidence available today does not support describing the current situation as an intelligence explosion. That term usually refers to a hypothetical feedback loop in which an AI system improves itself, the improved version becomes even better at creating further improvements, and the cycle accelerates until capability increases far beyond ordinary human control.
What Anthropic has disclosed is significantly more limited because humans still control objectives, resources, deployment decisions and the overall research programme. Claude is making those humans considerably more productive, and in some cases it can complete long and complex pieces of work with relatively little intervention, but Anthropic’s own automation framework says Claude has not reached full autonomy in any measured area of AI R&D.
The development should therefore be discussed without either extreme. Calling Claude a fully self-improving intelligence exaggerates what has happened, while dismissing its rapidly increasing role as ordinary automation understates how much the development process itself is changing.
There are compelling reasons researchers will continue using AI in AI development despite the risks. The productivity gains can be enormous, and the same capabilities that accelerate frontier research can also be applied directly to safety testing and scientific discovery.
Potential benefits include:
These benefits explain why a simple prohibition on AI-assisted R&D is unlikely to be attractive to frontier laboratories. The more realistic challenge is to ensure that oversight, validation and transparency improve alongside the productivity gains rather than becoming an afterthought.
Anthropic is not developing Claude in isolation. OpenAI, Google DeepMind, Meta, xAI, Chinese laboratories and open-model developers are all competing to improve their systems, which means a breakthrough in AI-assisted research at one organisation creates pressure for others to achieve the same advantage.
The competition is therefore becoming more complicated than a race to build the most capable model. Frontier laboratories are also competing to build the best system for building future models, including coding agents, automated evaluation systems, research assistants and internal infrastructure that allows human scientists to move more quickly.
If one laboratory can conduct twice as many meaningful experiments as another with a similar number of researchers, that productivity advantage can compound across several development cycles. The same dynamic also helps explain why recent calls from AI leaders to slow frontier development are difficult to implement: even organisations concerned about safety have powerful incentives to continue improving the systems that accelerate their own research.
What makes this development fascinating is not the dramatic idea that Claude has suddenly replaced the people who created it, because that has not happened. The more meaningful change is that AI is becoming a working participant inside the organisations that understand these systems better than almost anyone else.
That could be tremendously useful because talented researchers supported by capable AI may be able to explore ideas that would otherwise take much more time, money and manpower. However, human participation should remain deeper than simply providing approval at the end of the process. Researchers need enough involvement to understand the reasoning, question unexpected results and recognise when an apparently impressive output does not actually solve the problem that matters.
The most valuable future would therefore not be one where humans disappear from AI research. It would be one where AI expands what human researchers can investigate without weakening their ability to understand and control the systems they are building.
From an engineering perspective, the most significant part of Anthropic’s disclosure is not merely that Claude leads 26% of measured R&D tasks. It is the speed at which AI involvement has grown and the possibility that stronger models will make future model development increasingly efficient.
If that trend continues, the role of the human AI researcher may change substantially. Researchers could spend less time writing implementation code and more time selecting objectives, designing evaluations, interpreting evidence and deciding which systems are safe enough to progress. That would resemble the transformation already occurring in software engineering, where experienced developers increasingly supervise AI-generated implementation rather than manually typing every component.
The central technical challenge will be ensuring that oversight scales as quickly as automation. Increasing the number and independence of AI research agents without equally capable monitoring would create a gap between how quickly a laboratory can build new technology and how confidently it can understand what those systems are doing.
Claude helping build future versions of Claude is one of those developments that can easily be exaggerated, but it would be equally misleading to dismiss it as ordinary productivity software. Anthropic still controls the research programme, human researchers supervise the work, and the company explicitly says Claude has not achieved full autonomy in measured AI R&D. At the same time, Claude now leads a meaningful portion of that work and participates in the overwhelming majority of Anthropic’s measured research workflow.
The important shift is that AI has moved from being only the result of AI research to becoming an increasingly important tool inside AI research itself. If future models become better at writing code, planning experiments, interpreting results and eventually proposing research directions, the speed of AI development may depend increasingly on how capable AI becomes at helping create its own successors.
That does not mean recursive self-improvement has arrived, and it certainly does not mean an intelligence explosion is underway. It means the early pieces of a potentially important feedback loop are becoming visible, which makes transparency and strong human oversight more valuable rather than less important.
For now, Claude is still building the future alongside humans rather than replacing them in the development process. The question worth watching is how that balance changes if the next generation can perform substantially more of the research independently, because that is the point where “AI helping build AI” could become something much more consequential.
Claude is participating extensively in Anthropic’s development work, but humans still control the overall process. Anthropic says Claude leads approximately 26% of measured AI R&D tasks while human researchers provide objectives, supervision and final judgement, so the system is helping build future AI rather than independently creating its own successor.
Anthropic uses an automation scale in which “AI leads” means the system can complete most of a defined task from a high-level instruction while a human supervises. It does not mean Claude controls 26% of Anthropic’s company decisions or determines independently what future models should become.
Recursive self-improvement refers to a much more advanced situation in which an AI system can substantially improve or create a more capable successor, which then becomes better at producing further improvements. Anthropic says Claude has not reached this stage and notes that such an outcome is not inevitable.
No. Anthropic explicitly says Claude is not fully autonomous in any measured subset of its AI R&D work. Human researchers remain responsible for supervision, strategic choices, resource allocation and deployment decisions.
AI can shorten coding, experimentation, analysis and evaluation cycles, allowing researchers to test more ideas in less time. If those productivity gains continue improving with each model generation, they could materially accelerate both AI development and scientific research.
AI-assisted development is not inherently dangerous, but increasing autonomy can create risks involving oversight, speed, transparency and competitive pressure. The key challenge is ensuring that monitoring, evaluation and human expertise grow alongside the amount of research delegated to AI.
Satya Hemanth is the founder of H View and writes on careers, sports, leadership, digital trends, and practical decision-making. His articles focus on clear explanations, real-world examples, and useful insights for students, young professionals, and everyday readers.
Share your real experience and help other readers decide better.
No community views yet. Be the first to share yours.
Open LinkedIn for a few minutes and you will probably come across a colourful graphic…
Harika October 6, 2026 
When an employee resigns, many organisations move quickly into replacement mode. The manager informs HR,…
Harika October 6, 2026 
For many corporate employees, the workday begins long before they actually start working. They wake…
Harika October 5, 2026 
Many projects begin with an assumption that sounds reasonable on paper: the client will explain…
Harika October 1, 2026