
Robots.txt and Noindex: Two Different Reasons Search Engines May Miss a Page
Understand robots.txt versus noindex, why blocked crawling can hide indexing instructions, and how to investigate missing pages without risky changes.
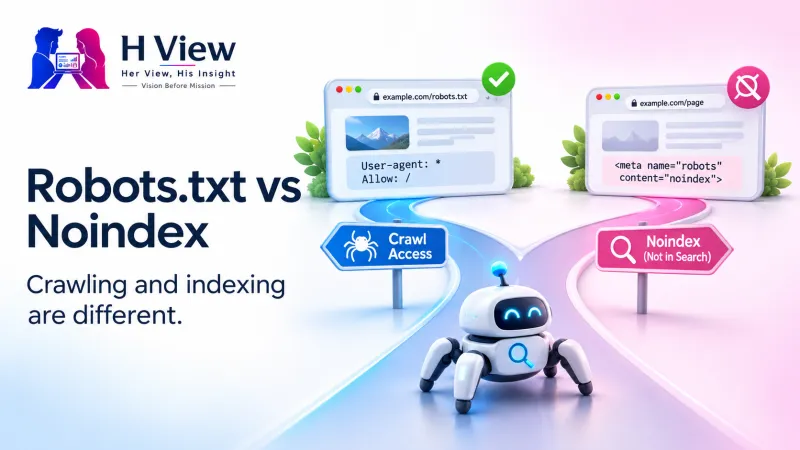
Robots.txt controls which URLs compliant crawlers may fetch, while noindex tells a supporting search engine not to include a page in its index. They solve different problems. If crawling is blocked, Google may be unable to read a page’s noindex instruction, so combining both without a clear purpose can produce confusing search results.
Publishing a page, submitting a sitemap and seeing it appear in Google are separate events. That is why a website can show hundreds of public pages while Search Console reports a different indexed total. Some exclusions are intentional, some are technical mistakes and some reflect search-engine decisions. Treating every missing page as a robots.txt problem leads to changes that may not address the actual reason.
This guide explains the distinction through practical examples for website owners and students. It focuses on Google’s documented behaviour and labels examples as examples. It is not a promise that removing a restriction will produce indexing, rankings or traffic, and it does not suggest exposing private pages to make an indexing report look better.
What is the difference between discovery, crawling and indexing?
Discovery means the search engine learns that a URL exists, perhaps from a link or sitemap. Crawling means fetching a resource so its response and content can be examined. Indexing involves processing a page and deciding whether to include it in the searchable collection. A URL being known does not mean its current contents have been fetched or that it has been selected for indexing.
For a small business, think of a newly published service page. The page may be accessible to visitors while Google has not revisited the site’s links or sitemap. Alternatively, Google may fetch it and find a noindex instruction. These situations can look the same in a manual search, but the corrective action is different. Start with the exact URL and the available inspection evidence.
Discovery
The URL becomes known through links, sitemaps or another discovery route.
Crawling
The crawler requests an accessible URL and examines its response.
Indexing
The engine processes the page and decides whether it belongs in its index.
What does robots.txt actually control?
A robots.txt file supplies crawl instructions for supported user agents. A rule can prevent a compliant crawler from fetching a matching path, but that does not make the resource private. Google’s robots.txt introduction explains that a blocked URL may still be discovered through links and appear without the crawler having read its contents. The important distinction is between a known address and fetched page content.
Use deliberate path-level rules for a defined crawling purpose rather than copying another website’s file. A misplaced broad rule can affect much more than one page, especially when a development setting is carried into production. Before editing, save the existing file, identify the intended crawler and write down which exact URLs should change behaviour. Test representative paths rather than checking only the homepage.
 Also readPHP Website Showing a Blank Page or 500 Error? Where to Start→
What does noindex do?
A noindex instruction can be provided in an HTML robots meta tag or an HTTP response header. Google’s noindex documentation explains that Google must access the page to detect the instruction. A developer can inspect the returned HTML and headers to check how it is being served, rather than relying only on a content-management setting that may not match the live response.
An HTML example is <meta name="robots" content="noindex">. A response-header example is X-Robots-Tag: noindex. These are teaching examples, not instructions to add them to your public articles. Headers are particularly important to investigate when a page looks correct in the editor but an indexing inspection reports noindex from an unexpected source.
| Control | Primary purpose | Common misunderstanding |
|---|---|---|
| Robots.txt disallow rule | Restrict fetching by compliant crawlers. | It does not guarantee that a known URL disappears from search. |
| Robots meta noindex | Request exclusion from indexing through the HTML response. | The crawler must be able to read the instruction. |
| X-Robots-Tag noindex | Provide an indexing instruction through a response header. | It may be set outside the page editor. |
| Authentication | Control access to protected content. | Privacy should not depend on a crawler voluntarily obeying a text file. |
Why can blocking crawling prevent noindex from working?
Imagine a demonstration page that was publicly accessible and has links pointing to it. The owner adds noindex to the page but also disallows its path in robots.txt. If Google obeys the crawl restriction, it cannot fetch the updated response to observe noindex. Google specifically warns about this combination in its indexing documentation. A known URL may therefore remain visible in a way the owner did not expect.
The right response depends on the purpose of the page. If it is harmless public material that should be excluded from search, the noindex instruction needs to be readable. If the page contains confidential data, protect access first rather than opening it just to help a search crawler. Where public exposure has already occurred, involve the site administrator in an appropriate removal and access-control plan.
How should you investigate a missing article?
Use Search Console’s URL Inspection for the precise canonical URL you expect people to find. Note the reported indexing reason, last crawl and any differences between the inspected history and a live test. A live test establishes current accessibility and some technical conditions; it is not a guarantee of future indexing. Read the result as evidence about that URL rather than a score for the entire website.
Next, check the public response while logged out. Confirm that it is the intended page rather than a login screen, redirect destination or error page. Inspect robots instructions in both the HTML and HTTP headers. Check whether a canonical tag points elsewhere and whether the page is actually linked from the site. An editor preview and an ordinary visitor request can have very different access conditions.
The Page indexing report documentation helps distinguish exclusion categories. A duplicate or alternate canonical issue is not the same as a noindex exclusion, and a page that has not been crawled needs a different investigation from one that has been crawled but not selected. Keep the report reason attached to the actual URL in your audit notes.
An illustrative audit of three service pages
Suppose a business launches three service pages. The first contains a noindex tag left over from development, the second redirects to an older service address and the third is accessible but has not yet been crawled. The owner searches Google, sees none of the three and assumes that the sitemap failed. That single conclusion would conceal three different situations.
A careful audit records each URL, its response, crawl permission, indexing instruction and canonical destination. The first page needs a deliberate decision about removing noindex; the second needs the correct final URL and redirect plan; the third needs discovery and follow-up monitoring. This is a hypothetical exercise, not a measurement of HView’s current pages or a promise that these are the only possible causes.
Does a sitemap force Google to index a page?
No. Google describes sitemap submission as a hint, not a guarantee that it will fetch or use every listed URL. Its sitemap guidance is useful for discovery, but a sitemap does not override access restrictions or indexing instructions. Keep it aligned with the canonical public pages you actually want considered.
Do not add drafts, private reports or duplicate query-string versions simply to increase the sitemap total. A larger count is not a success measure on its own. The more useful questions are whether important pages are discoverable, technically eligible and worth indexing for their intended audience. Fixing a crawl directive cannot replace distinct content or a useful internal linking structure.
What should you check after making a correction?
Recheck the live response and representative URLs affected by the change. If a CDN or cache is involved, verify what ordinary visitors and crawlers can actually receive after the update. Record the change time and use an appropriate URL inspection or recrawl request for important pages. Avoid repeatedly changing unrelated settings while waiting for search reporting to catch up.
For deleted or relocated pages, plan the correct status or redirect rather than using noindex as a substitute for an information-architecture decision. For confidential material, review access controls with the owner. Search cleanup, navigation quality and data protection are connected operational concerns, but they should not be collapsed into a single robots.txt edit.
 Also readWhat Makes a Useful Landing Page? A Guide for Small Businesses→
Her View
A website owner needs a clear explanation of what a missing page means for readers. Start with important journeys and useful public pages instead of chasing a perfect indexed-page percentage. Some pages should stay private or out of search, and protecting those boundaries is part of a trustworthy website.
His Insight
Separate the layers before choosing a fix. Record discovery, response status, crawl access, noindex and canonical behaviour for each affected URL. This turns an anxious general complaint into a series of checks that another developer can repeat and assess.
H View Verdict
Use robots.txt for crawl control and readable noindex instructions for appropriate search exclusion. Never treat either as a password system, and do not expect sitemap submission to override them. Investigate the reason attached to the page, then verify the specific correction.
Frequently asked questions
Can I put a noindex instruction inside robots.txt?
Google does not support noindex rules in robots.txt. Use a supported meta tag or HTTP response header when appropriate, and make sure the crawler can access the response containing that instruction.
Should every page on my website be indexed?
No. Private areas, duplicates and pages without a useful standalone search purpose may not belong in the index. Decide which canonical public pages serve readers, rather than treating the largest possible indexed total as the goal.
Will removing noindex make a page appear immediately?
No. The search engine needs to revisit and process the page, and technical eligibility alone does not guarantee selection. Verify the live change and monitor the relevant report without promising a fixed indexing date.
Need help checking important URLs? Use the direct form on our technical SEO and analytics service page. Share public URLs and the reported exclusion reason, without sending account passwords or private search-console exports.
H View stories follow our editorial policy. Spotted an error? Tell us and we will correct it.
Rate this article
One tap is enough. No comment needed.
Was this article helpful?
Your answer goes straight to our editors.
Comments0
No comments yet. Start the conversation.